Choosing, Gating, and Escalating Agent Models on OpenRouter
If you ship coding agents, you keep facing the same decisions: whether to change the default model, whether a prompt edit should block merge, whether a cheap model’s shaky answer should call a more expensive one. Leaderboards do not answer those questions—they average someone else’s tasks. Your agent is a narrow workload with multi-step tool calls and retries you still pay for. On 2026-10-01 OpenRouter published three operational guides: pick models by plotting cost against quality on your examples, gate pull requests on a fixed LLM eval set in CI, and escalate by self-reported confidence.[1][2][3] This post wires them into one pipeline, then adds the official routing/fallback docs, classic FrugalGPT / RouteLLM numbers, and the evaluation-reliability posts already on this site. It is written for engineers building agent products, not as an OpenRouter brochure.
Related posts: Control the Harness, Control the Cost puts enterprise routing and bill ownership in the harness; Haiku 5.5 as subagent and DeepSeek Flash economics cover single-model price shapes; cost-inefficient coding-agent behaviors covers trajectory waste; agent evaluation reliability and CIR causal recovery ask what a score actually warrants. This piece stays on the select → gate → escalate operator loop.
Four strategies on one table—every later section is about when one cell breaks:
| Strategy | What you optimize | Typical signal | Main failure mode |
|---|---|---|---|
| Pick the leaderboard winner | “Strongest” | Public benchmark rank | Task mismatch; undercounts multi-step agent cost |
| Cost–quality frontier on your set | “Cheapest that clears the bar” | 20–50 own examples + usage.cost | Tiny sample; no margin for score swing |
| Gateway / market routers (incl. Auto) | “Swap models without rewiring” | Task class + market spend share | Market optimum ≠ your SLA; same slug, different providers |
| Confidence escalation | “Stay cheap when sure” | Structured confidence field | Uncalibrated self-reports; mixed with error fallbacks |
The short version: three layers, not one switch
- Selection. Per task, define a quality bar, measure cost per quality point on your own examples, take the cheapest model that clears the bar with margin.[1]
- Gate. Prompt, tool-schema, and agent-logic changes must pass a fixed eval set; the threshold comes from the floor of repeated runs on an unchanged branch—not a guessed 0.9.[2]
- Runtime. Error fallbacks (
modelsarrays / provider failover) and confidence escalation are different mechanisms: the first fires when a request fails; the second when the answer is valid but low-confidence.[3][4]
One line: leaderboards list candidates; your frontier sets the default; CI blocks regressions; confidence pays a premium per request. The rest of the post is mechanism.
Cost–quality frontier: your points, not their board
OpenRouter’s selection framework states the question cleanly: not which model scores highest, but which is the cheapest that is good enough.[1] Agent work is often narrow—triage a ticket, extract one field, escalate when unsure—so whether a mid-tier model matches a frontier model is a measurement the leaderboard will not make.
Three steps:
- Set the bar first. Compliance / healthcare / legal can sit high; high-volume support may accept “90% routine correct, 10% clean escalation.” Latency-sensitive work disqualifies “cheap and accurate but too slow” before cost enters.[1]
- Run cheap / mid / frontier on 20–50 of your own examples. One rubric for all. Exact match for deterministic tasks; LLM-as-a-judge for open-ended ones. Read cost from
usage.coston each response (OpenRouter includes it on non-streaming responses and on the final streaming message)—do not multiply list rates by guessed tokens.[1] - Take the cheapest clearer with margin above observed run-to-run swing. Re-run candidates or a fresh traffic slice; require the winner to beat the bar by more than that swing.[1]
Their illustrative table (catalog list prices as of 2026-09-18; tokens and scores illustrative) at an 85-point bar reads: GPT-5.6 Luna about USD 0.32 per 1K requests at score 82—out; Gemini 3.7 Flash about USD 1.09 at 89, clears by +4; Claude Opus 5 about USD 7.25 at 97, clears but costs several times more. Among clearers, Flash wins.[1]
Figure: three candidates on a cost-per-1K × quality plane; below the bar is disqualified, above it take the cheapest. Numbers from OpenRouter’s illustrative table[1].
Change the task, change the answer. Same article: support triage at bar 80 can stay on the cheap tier; code review at 88 needs mid-tier; compliance at 95 needs frontier.[1] Same method, different bars. Prices and versions move—they note four Gemini Flash versions between May and September 2026—so keep the script and example set and re-run when candidates or prices change.[1]
Boundaries:
- Too few examples. A handful is smoke only. Anthropic’s agent-eval guidance (cited in the CI post) starts from 20–50 simple tasks drawn from real failures.[2]
- Single-turn cost only. Agents pay for tool calls and retries; sum
usage.costover a full task run.[1] - Defaulting to board #1. On-site agent evaluation reliability shows model-ranking reliability is often far below fixed model–scaffold system ranking; stacking same-construction tasks barely helps.[5] Using a public board to set your agent default mismatches claim and measurement.
Gateway layer: provider routing, error fallbacks, Auto
Selection picks a logical model; production still lands on a provider endpoint. OpenRouter’s docs keep the pieces separate:
Provider selection. Default load balancing prefers endpoints without significant outages in the last 30 seconds, then weights stable candidates by the inverse square of price, with the rest as backups.[6] You can set provider.order, disable backups with allow_fallbacks: false, require full parameter support with require_parameters: true, sort by price / throughput / latency, and express soft preferences via preferred_min_throughput / preferred_max_latency.[6]
Model error fallbacks. A models array tries IDs in order when the primary errors (downtime, rate limits, moderation refusals, context-length validation, and related failures). Billing follows the model that ultimately answered; the response model field names it.[4] On the Anthropic Messages endpoint, fallbacks accepts at most three entries and cannot combine with models.[4]
Auto Router (openrouter/auto). Classifies the prompt into roughly 30 fine-grained task types, ranks models by community spend share over a trailing 7-day window for that type, applies your cost_tier (low / medium / high / xhigh / max), and builds a primary-plus-fallback list. If classification or rankings are unavailable, it degrades to a default set so routing infra does not fail the request.[7] Multi-turn sessions prefer the prior model (session_id or message fingerprint) until the task type shifts.[7]
None of these is confidence escalation. OpenRouter states explicitly that models fallbacks fire on errors, not on valid low-confidence answers—you write that path yourself.[3]
A hard operational cut from a high-volume OpenRouter practitioner post (later on HN): the same model slug can differ sharply across providers on tool-calling benchmarks—the author cites DeepSeek V4 Flash at about 81% vs 58% on TAU-Bench Airline between first-party and DigitalOcean; quantization filters are a poor quality proxy; reasoning.effort is silently ignored on some hosts; pinning three “reliable” providers still collapsed into collective 429s two weeks later.[8] That is why the CI guide pins provider.order to one provider with allow_fallbacks: false for eval traffic—otherwise a provider swap looks like a prompt regression.[2]
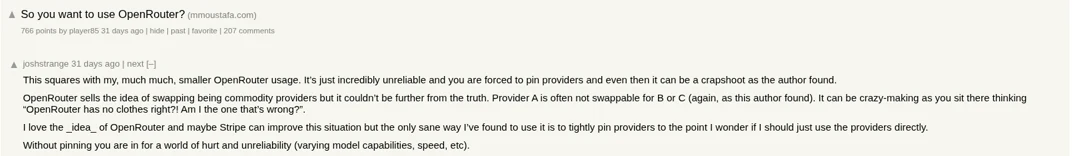
Screenshot: Mo Moustafa’s practitioner notes drew 766 points and 207 comments on HN; the top commenter, with much smaller usage, says pinning providers was the only way to keep it reliable (Hacker News, captured Oct 2026)[8]
CI gates: treat evals like merge-blocking unit tests
One system-prompt edit can teach a support agent that the refund window is 30 days when policy says 14—ordinary CI never reads what the model said.[2] Gating works like a failing unit test: keep a fixed eval set in the repo, run it when relevant files change, exit non-zero when the pass rate falls below threshold.
Four-step skeleton (details follow OpenRouter’s tutorial):[2]
- Filter at the job level, not with workflow-level
on.pull_request.paths. When GitHub skips an entire workflow via path filters, associated checks stay Pending and block required merges; a job skipped byifcounts as passing, so unrelated PRs can merge.[2] Usedorny/paths-filterto emitagent: true/false, and have the eval jobneedsit. Mark bothchangesandeval-gaterequired—if only eval-gate is required and the filter job fails, eval is skipped and shows green.[2] - Keep the eval set beside the prompts, changed in the same PR. Cases carry
mustMention/mustNotMention; allow synonym lists so “a person” is not a false fail when you meant “human”.[2] Protectprompts/andeval-sets/with CODEOWNERS and require code-owner review—otherwise the fastest fix for a red gate is weakening the test.[2] - Sample each case multiple times and take a majority; exit 1 means quality regression, exit 2 means the eval could not run (empty set, bad flags, provider timeout)—so an empty
[]set cannot produce a NaN pass rate that still clears.[2] - Measure the threshold from the floor: run the set six times (more if you can) on unchanged
main, take the lowest pass rate, set the threshold at or below it. With three cases the pass rate can only be 0 / 0.33 / 0.67 / 1.00, so 0.9 means “all three must pass”—another reason to grow toward 20+.[2]
Figure: path filter → run evals → compare to a measured threshold; exit 1 vs 2 separates regressions from infra failure. Based on[2].
Noise control: check assertions first; then check whether the model lists temperature/seed in supported_parameters—on 2026-09-18 OpenRouter’s catalog had about 445 models, 267 listing both, roughly two in five missing one or both; Claude Sonnet 5 silently ignores temperature.[2] Absorb remaining variance with odd-sized majority samples. When a PR fails by one case, re-run the same set on main: if main fails too, it is noise; if main passes, treat it as a regression.[2]
Against on-site eval posts: reliability stresses that reliability is claim-dependent—system ranking can be solid while model ranking is not. A CI gate claims “this prompt+harness did not regress,” not “the model got stronger.”[5] CIR warns that average success rates flatten rescue vs harm; string assertions can look stable while one harmful case is masked—keep per-sample traces (the tutorial prints ./x).[9][2]
When the agent calls tools, the guide points to Ori Eval: assert “called lookup_order, did not call issue_refund,” and grade with a different model family after human calibration.[2] Platforms (DeepEval / Braintrust / Arize / Galileo) add history and dashboards; the exit-code pattern stays the same—start with the script.[2]
Confidence escalation: ranking works, absolute numbers do not
Sending every request to the strongest model pays frontier rates for work a cheaper model would have handled; fixed keyword / task-type rules rot as traffic shifts.[3] Confidence escalation sits between: force a 0–1 confidence field via structured outputs, keep answers above the threshold, escalate below it.[3]
The critical clarification—OpenRouter spends almost a full section on it: a self-report is not a calibrated probability. 0.85 is not “85% likely correct,” and 0.85 is not interchangeable across prompts or models. What you can use is ranking: bin your own traffic by score and check that lower bands err more often than higher ones.[3]
Their arithmetic illustration (200 representative requests—not your cutoff): ≥0.95 about 41% of traffic with about 1% error; 0.85–0.94 about 27% / 4%; 0.70–0.84 about 18% / 11%; 0.50–0.69 about 9% / 34%; below 0.50 about 5% / 61%. Error climbs sharply below 0.70, so 0.7 is the candidate cutoff: about 14% escalate, and error on kept answers falls from roughly 10% overall to about 4%.[3] Raising to 0.85 also escalates the 0.70–0.84 band (about 32% escalate) and drops kept error toward about 2%—accuracy, cost, and latency move together.[3]
Figure: cheap model emits structured confidence → keep or second-call. Illustrative bands from[3]; distinct from models error fallbacks.
Implementation notes:
- Force
answer/confidencewithresponse_format+ JSON Schema; put the 0–1 range indescription, notminimum/maximum(Anthropic strict mode does not support those numeric constraints).strict: trueenforcement varies—validate after parse.[3] - Set
provider.require_parameters: true, or endpoints that lack structured outputs may still receive the request and ignore the parameter.[3] - Either retry the stronger model inside one function (policy in one place) or treat the cheap call as a logged first pass (easier re-tuning). Either pattern can stack
modelserror fallbacks underneath.[3] - From day one log score distribution, escalation rate, and error rate on non-escalated answers. Retune when either tier changes or traffic gets harder.[3]
Misuses:
- One global threshold for every task type—refund FAQ vs “will I be charged if I cancel” do not share the same cost of being wrong.[3]
- Writing self-reported 0.9 into an SLA as “90% correct”—the claim does not follow.[3]
- Replacing eval gates with confidence—when calibration drifts you will be confidently wrong at scale. Gates test whether a change broke behavior; escalation decides whether one request pays more.
Academic backdrop: cascades and learned routers already priced this
FrugalGPT (Stanford, 2023) cascades LLMs with a scorer that accepts or queries the next model—up to about 98% cost cut while matching the best single LLM, or about 4% accuracy gain vs GPT-4 at equal cost (dataset-dependent; HEADLINES matching GPT-4: about 33.1 → 0.6 cost units, about 98.3%).[10] Same shape as confidence escalation, with an external scorer instead of a self-report.
RouteLLM (Berkeley / Anyscale et al., 2024) learns a pre-call strong/weak router from preference data; public benches show over 2× cost cuts, e.g. matrix-factorization CPT(50%) about 13.4% strong calls on MT Bench after augmentation (vs about 50% random).[11] RouteLLM is your trained router; OpenRouter Auto is a live market spend index.[7][11] Either way you still owe your bar, floor, and calibration.
Nesting the three layers in one agent pipeline
Selection, gates, and escalation are gates on one line, not three side projects. A common wiring:
- Offline: refresh a default-model table (task type → model ID → quality bar → last calibration date). The table lives in git; table edits are PRs.
- At merge: if the PR touches
prompts/, tool schemas, agent logic, or the eval itself, CI runs the fixed set on the current default (or a PR-nominated candidate); failing the bar blocks merge.[2] - Online: the default model returns structured confidence; low scores escalate. Error paths use a separate
modelsfallback so timeouts are not treated as “low confidence.”[3][4] - Weekly: when list prices or primary candidates change, re-run the frontier script; watch whether non-escalated error rate climbs.[1][3]
The default-model table + CI gate + escalation threshold are the harness control plane you can commit (Control the Harness). Routing savings can still be eaten by trajectory waste (cost-inefficient behaviors). Grow the eval set one case per production incident; before about 20 cases, explain the threshold as “how many may fail,” not fake precision.[2] Pin providers during calibration; in production use a short order with controlled fallbacks and watch per-provider boards.[8][2] Use Auto while exploring; once the bar is contractual, return to explicit model IDs plus your frontier.[7]
Decision framework and checklist
Per-task default (selection)
- Quality bar, latency ceiling, and cost-of-error written down (who yields when they conflict)
- 20–50 examples from real failures / real traffic, not a public-bench subset
- At least three model tiers scored; cost from
usage.cost; one rubric - Winner’s margin ≥ observed swing; script and set in the repo
Before production (gate)
- Eval set co-located with prompts; CODEOWNERS + required owner review
- Job-level path filter; both
changesandeval-gaterequired - Threshold ≤ floor measured on
main; odd sample count; provider pinned - Exit 1 vs exit 2 separated; fork-PR secret policy decided
Runtime (escalation + fallback)
- Error fallback and confidence escalation on separate code paths
- Confidence from schema, validated after parse;
require_parameters: true - Thresholds calibrated per task type; monitor non-escalated error rate
- Multi-provider same slug: trust workload-matched boards, not quantization labels[8]
When to skip a layer
- Extremely narrow tasks with tiny error cost: a cheap default from selection may be enough—no second call
- Regulated “every answer must trace to a fixed model version”: tighten Auto and multi-provider balancing to pins
- Eval set still thrashing: soften the gate to warn-only until the floor stabilizes, so the team does not learn to ignore red Xs
Minimal reproducible steps (skeleton you can stand up in a day)
- Pull about 30 production examples; label gold or must/must-not strings into
eval-sets/core.json. - Write a script that only swaps the model string, reads
usage.cost, scores, and prints score / cost-per-1K / cost-per-point; run three candidates and lock a default.[1] - Wire the same set into GitHub Actions: paths-filter +
node scripts/run-evals.mjs --samples 3; six runs onmainfor the floor, then--threshold.[2] - Add structured confidence to the default model; bin about 200 historical requests for a first cutoff; escalate to one mid tier up, not straight to the most expensive.[3]
- Ship three charts: default score distribution, escalation rate, non-escalated error rate; re-run step 2 the week models or prices move.
Keep code blocks free of shell variable sigils; pass secrets via the environment name OPENROUTER_API_KEY. When mirroring OpenRouter’s CI sample, sync provider.order with --model.[2]
Boundaries and counterexamples
- Treating illustrative numbers as targets. Flash at USD 1.09 per 1K, threshold 0.7, 98% savings—are someone else’s arithmetic or an older market; draw your own curves.[1][3][10]
- Green gate = good product. A three-case string gate prevents known regressions, not capability ceilings; grow the set with incidents.[2]
- Auto as product strategy. Market spend share optimizes what the community pays for, not what your SLA requires.[7]
- Pins as permanent HA. Three “reliable” providers have failed together in practice; keep error fallbacks or degraded copy, not eternal allowlists.[8]
- Confidence instead of human review. Escalating to a stronger model can still be wrong on high-stakes tasks; human or tool checks remain on the path.[3]
Once selection, gates, and escalation stack, OpenRouter looks more like a swappable substrate: list prices and usage.cost make the frontier computable, provider and models fallbacks recover from errors, Auto offers a market index—but the bar, the floor, and the calibration still have to live in your repository.
References
- OpenRouter, Cost vs. Quality Tradeoff Framework for Agent Models (2026-10-01) ↩
- OpenRouter, How to Gate Pull Requests on LLM Evals in CI (2026-10-01) ↩
- OpenRouter, Confidence Thresholds for Model Escalation Routing (2026-10-01) ↩
- OpenRouter Docs, Model Fallbacks ↩
- On-site, Agent Evaluation Reliability; paper arXiv:2610.00651 ↩
- OpenRouter Docs, Provider Routing ↩
- OpenRouter Docs, Auto Router ↩
- Mo Moustafa, So you want to use OpenRouter? (2026-09-07); HN item 49621546 ↩
- On-site, CIR: do not judge harness recovery by average success alone; paper arXiv:2610.00372 ↩
- Chen, Zaharia, Zou, FrugalGPT (arXiv:2305.05176) ↩
- Ong et al., RouteLLM (arXiv:2406.18665) ↩
- On-site cross-links: Control the Harness, Control the Cost, Haiku 5.5 subagent cost model, DeepSeek Flash economics, coding-agent cost-inefficient behaviors